Once the United States and China are removed, who can actually build AI, keep it running, and connect it to domestic industry? This article gives a direct answer through a new global AI ranking. Instead of a broad Stanford-style index, it uses three things a reader can feel. First, does a country have Korea AI models or equivalent models that can be sold as a service or released as open weights? Second, does it have the GPUs, capital, and research organizations to keep training and operating them? Third, can it connect AI to domestic administrative, industrial, and language data rather than only buying data from elsewhere?
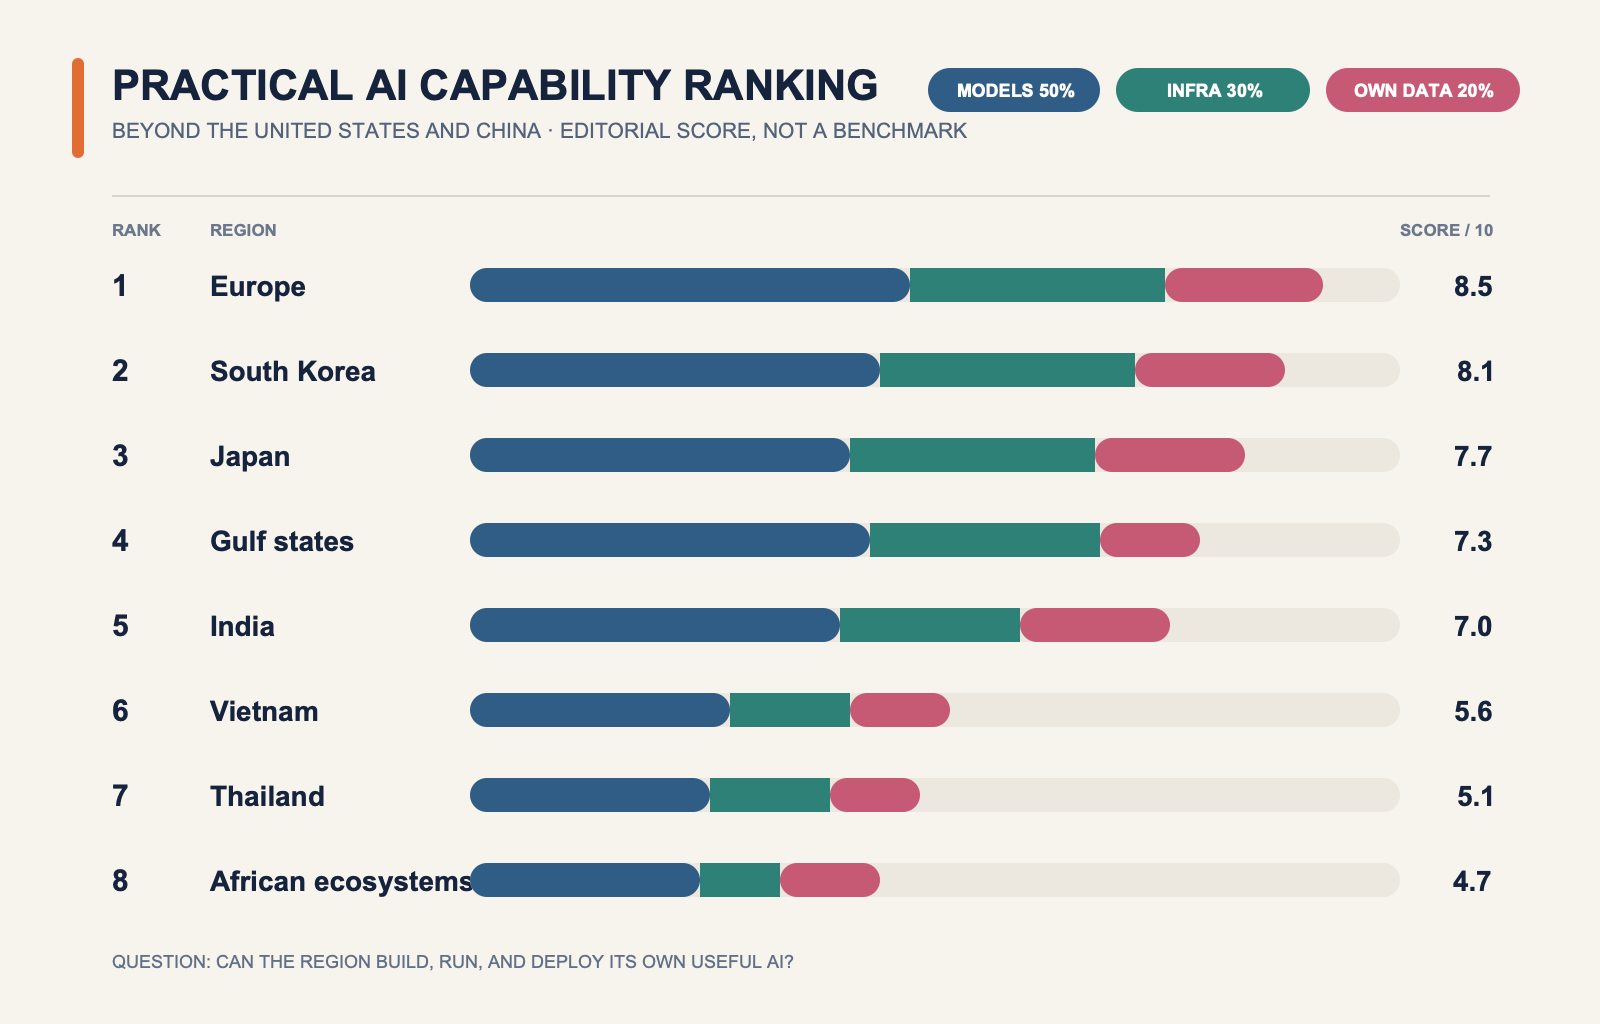
This is not an official international ranking. It is an editorial capability ranking that separates countries which merely buy U.S. or Chinese models from those that have acquired some ability to secure models, infrastructure, and data for their own language and industries. The weights are 50% model ownership, 30% AI GPU infrastructure, capital, and research organizations, and 20% domestic-data capacity. Europe is evaluated as a shared market, research, and computing bloc rather than as one country.
The Answer First: Practical AI Capability Beyond the U.S. and China
The scores below are not decimal benchmark results. They are weighted A-to-C judgments against the three tests above. A means a region can produce and operate that layer with domestic leadership; B means representative models or programs exist but supply-chain or scale gaps remain; C means local adaptation and deployment are possible but large-scale autonomy is not. A decimal such as 8.5 only expresses the weighting; it is not a precise measurement of model performance. The score does not say how many points a model is behind ChatGPT. It says whether a country or region can build a useful model, continue operating it, and put it to work on its own data.
| Rank | Region or country | Models 50% | Infrastructure 30% | Domestic data 20% | Practical judgment |
|---|---|---|---|---|---|
| 1 | European Union bloc | A- | A | A- | The thickest non-U.S./China bloc: Mistral-family models plus large research, industrial, and shared-compute capacity |
| 2 | South Korea | B+ | A | A- | Not a global frontier-model leader, but Korean models, HBM, manufacturing data, and public GPU support are moving together |
| 3 | Japan | B | A- | A | A durable path centered on Japanese language, manufacturing, and public-sector sovereignty rather than global model headlines |
| 4 | Gulf states, led by the UAE and Saudi Arabia | B+ | A- | B | Falcon, Jais, ALLaM, and exceptional GPU, energy, and capital strength; a thinner research and domestic-data base |
| 5 | India | B | B | A- | Major talent, public digital rails, and language markets, but limited depth in frontier GPUs, chips, and large domestic models |
| 6 | Vietnam | C+ | C | B | Fast progress in Vietnamese models and national data strategy, with large-scale training infrastructure still being built |
| 7 | Thailand | C | C | B- | Thai open models such as Typhoon and public deployment exist, but compute and capital remain small |
| 8 | African regional ecosystems | C | C- | B- | Language communities, mobile, and fintech data are assets, while power, GPUs, and capital vary sharply country by country |
The point of placing Europe first is not that one European company beat GPT. Europe’s score combines firms such as France’s Mistral, research institutions across countries including Germany, France, and Italy, industrial data, and the EU AI Factory program. Korea reaches second not because one Korean model tops every leaderboard, but because semiconductors and manufacturing data are attached to the model effort.
Test One: Is There a Model You Can Sell or Open and Use?
The first test is simple. Does a country have a model good enough to use in its language and enterprise workflows? If not, does it at least have an open model whose weights, code, and technical documentation let developers adapt it into a domestic service? We do not count the number of derivative repositories on Hugging Face; fine-tuned copies of the same base model would inflate a country’s apparent strength. This test counts only representative models that are sustained as commercial APIs or are released with public weights, code, or technical documentation.
| Region or country | Representative models and evidence | Model judgment |
|---|---|---|
| Europe | France’s Mistral Large and Mistral Small families, alongside multiple open-weight releases | The only non-U.S./China bloc visibly present in the global commercial-model market. It is still not as deep as the leaders: Stanford’s 2024 count showed Europe with three notable models. |
| South Korea | NAVER HyperCLOVA X commercial services, LG AI Research EXAONE 4.0 open 32B, telco and national-project models | Korea has a usable Korean-language layer in both commercial and open forms. There is not enough basis to call it equivalent to the top global closed frontier-model group. |
| Japan | LLM-jp open models, GENIAC-supported Japanese LLMs, and PFN–NICT–Sakura Internet collaboration | Japan is building sovereign models for Japanese, manufacturing, and public use rather than trying to dominate the English-language frontier. LLM-jp’s work includes a 172B open beta produced by an academic and industry community. |
| Gulf states | UAE Falcon H1 and Falcon Arabic, Jais; Saudi Arabia’s ALLaM 34B | The Gulf has unmistakable Arabic-model and open-model presence. The UAE in particular also uses open releases as a talent, diplomatic, and ecosystem strategy. |
| India | Indian-language models from Sarvam and Krutrim, plus IndiaAI’s model, data, and tools platform | Models for a vast multilingual market are expanding. India remains a catch-up group in the global performance race for very large general-purpose models. |
| Vietnam and Thailand | Vietnam’s PhoGPT; Thailand’s Typhoon-7B and later Thai-language models | Both meet the basic condition of not leaving their national language entirely to foreign models. Their model size, training resources, and enterprise-deployment breadth are far below the upper group. |
| Africa | Distributed open research and translation communities such as Masakhane | Africa is not one country. Its common problem is building training and evaluation data for more than 2,000 low-resource languages. |
This is why Europe ranks first and Korea second on the model-centered reading. Europe has a model business that can sell to global customers through Mistral. Korea has both HyperCLOVA X and EXAONE as commercial and open Korean-model layers. Japan, the Gulf, and India have credible models, but their current strength is more concentrated in language regions, state programs, or local markets than in the broad global general-purpose market.
Test Two: Do GPUs, Chips, Money, and Researchers Keep Arriving?
Releasing one model is different from building the next generation two years later. This test asks how many GPUs can be secured, whether capital and power can expand data centers, and whether universities, labs, and companies form a continuous pipeline. AI GPU infrastructure is not just a server purchase; it includes energy, networking, operations talent, and long-term funding.
- The European Union bloc has the broadest public research base and shared infrastructure. In October 2025, the European Commission announced 19 AI Factories in 16 member states. Its advantage is that startups, universities, and SMEs can use a common infrastructure layer. Its weakness is continued dependence on U.S. supply chains for much of the highest-end GPU design and cloud capacity, plus slower cross-country decisions.
- South Korea does not design the leading training GPUs, but it has HBM, memory, foundry, and industrial-supply-chain capacity. The Ministry of Science and ICT said Korea would secure a cumulative 37,000 GPUs by 2026, including 15,000 through government procurement, while sovereign-AI projects receive GPU and data support. The claim is not that every chip is domestic; it is that Korea has unusually strong physical links between AI compute and industrial strategy.
- Japan supports compute for foundation-model development through GENIAC and is trying to join government, research institutes, telecoms, and manufacturers into one ecosystem. Sixteen projects were selected for its fourth support cycle in 2026. Japan’s strengths are capital, manufacturing, and institutional depth; its gaps include GPU supply and product speed relative to U.S. platforms.
- The Gulf is the most aggressive capital-led challenger. The UAE combines TII, which developed Falcon, with G42; Saudi Arabia combines SDAIA with large national investment plans. Money, energy, and political decision speed can procure GPUs and data centers quickly. Semiconductor manufacturing and the layered university-startup research ecosystem remain thinner than in Europe, Korea, or Japan.
- India has enormous engineering talent and a software industry, but remains import-dependent for the highest-end GPUs and chips. IndiaAI Compute is building a public cloud direction of more than 10,000 GPUs for public bodies, universities, and startups. It is a serious start, but not yet comparable with Europe’s shared supercomputing layer or the industrial supply chains of Korea and Japan.
- Vietnam, Thailand, and African ecosystems have less large-scale training compute, power capacity, and patient capital than their adoption needs suggest. Their realistic strategy today is not to resell foreign models unchanged, but to tune smaller open models on local language, government, finance, and manufacturing data while pooling access to scarce compute.
Test Three: Not “Do You Have Data?” but “Can You Train and Operate on Your Own Data?”
Domestic data is not a pile of web pages scraped or bought elsewhere. It is the data produced only in that country: administrative procedures, factory equipment, hospital records, financial transactions, logistics flows, local language, and customer support. Strong digitization does not automatically make that data useful for AI. Privacy, trade secrets, copyright, ownership between agencies, and weak quality must be overcome. Data becomes AI-ready only when it has lawful access, cleaning, labeling, and accountable operating ownership.
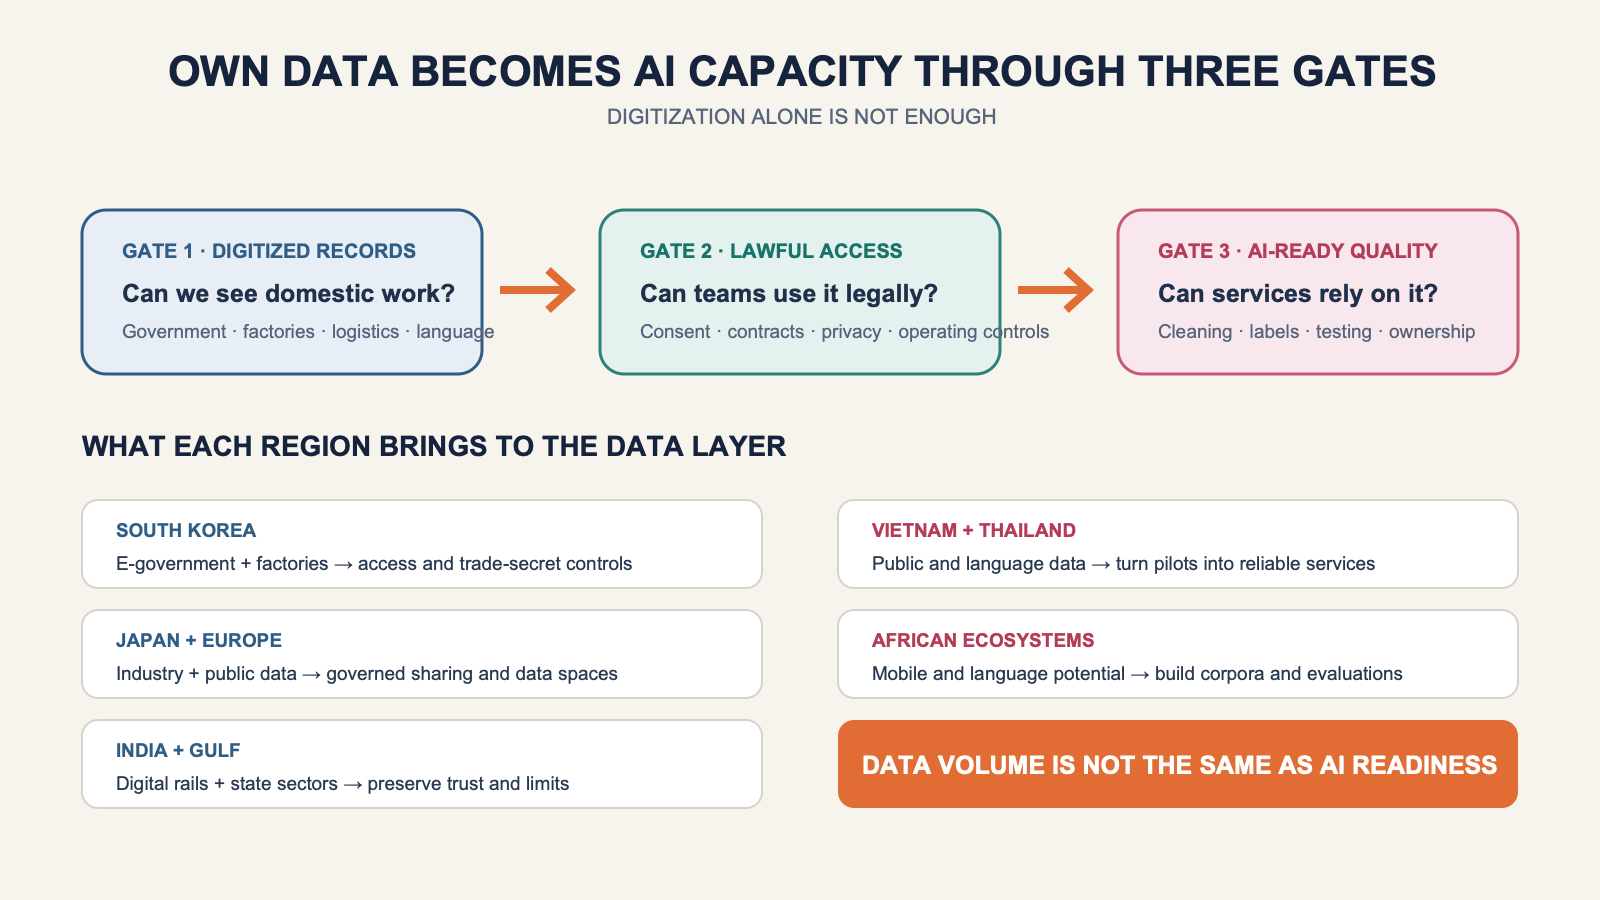
- Korea has dense e-government, telecom, finance, and manufacturing data. Equipment data from semiconductor, automotive, shipbuilding, logistics, and factories is especially hard for foreign models to reproduce. But this data is scattered inside companies and institutions, and privacy and trade-secret rules mean “the country has data, therefore a model can train on it” is false. Korea’s real contest is safe access, federated learning, de-identification, and field deployment.
- Japan also has deep manufacturing, robotics, precision-equipment, and public-record data. Older systems, company silos, and conservative procurement can slow combination of those assets. Japan’s Government AI GENAI connects laws, the Official Gazette, and ministry knowledge bases for controlled government use. That is a data-product approach rather than an assumption that every public record should be freely exposed.
- Europe is strong in automotive, machinery, medicine, finance, and scientific data. GDPR and the AI Act can slow some personal-data and high-risk use cases, but they do not mean Europe lacks data. Europe’s direction is to create trusted cross-border access through industrial data spaces and common rules. That could be a major advantage in manufacturing AI, while the cost of aligning rules and contracts remains a real drag.
- India has a major asset in digital public infrastructure such as Aadhaar and UPI, along with a huge multilingual and mobile market. If trust around privacy and public-data use is not maintained, scale becomes a social risk. India’s advantage is the breadth where consumer, administration, and payment data meet; its challenge is cleaning and evaluating that data fairly across many languages.
- The Gulf has state-led data in government services, energy, logistics, and finance, plus fast execution. Its absolute population and language-data scale, and its independent research ecosystem, are smaller than those of India and Europe. That makes Arabic, government, and energy domains more realistic targets than a generic data-volume contest.
- Vietnam, Thailand, and African regional ecosystems should not be dismissed here. Vietnam’s 2026–2030 National Data Strategy and AI law treat national, ministerial, and local databases as part of AI infrastructure. Thailand is connecting banking, telecom, tourism, public-service data, and Thai models. Africa has major potential in mobile, fintech, and local-language data but lacks corpora and evaluation sets for low-resource languages; communities such as Masakhane are therefore building the language-data layer itself.
How to Read This Ranking
The conclusion is not “Europe won and everyone else lost.” Outside the U.S. and China, Europe is the thickest composite bloc, Korea is the most industrially connected challenger, Japan has the most durable Japanese-language and manufacturing sovereignty path, the Gulf is the fastest state-led builder of money and GPUs, and India has the widest combination of talent, languages, and public digital rails. Vietnam, Thailand, and African ecosystems trail in frontier general-purpose models, but have more realistic opportunities where local language and public, financial, or manufacturing problems must be solved first.
Use this order when assessing a country’s AI position. First ask, “Does it have a representative commercial or open-weight model?” Then ask, “Can it fund GPUs, researchers, and training for a next generation?” Finally ask, “Can it legally and safely connect that model to domestic industrial data?” Only places strong in all three are moving from consuming AI to operating AI. This order is also more useful for a company evaluating Japan’s digital and AI market or a developer following the international agenda around AI safety.
Sources
- Stanford HAI, AI Index Report 2025 and 2026 Technical Performance
- European Commission, AI Factories Antennas, 2025
- Korea Ministry of Science and ICT, sovereign AI model and K-AI support and GPU procurement plan, 2026
- LG AI Research, EXAONE 4.0 official repository; NAVER, HyperCLOVA X
- Japan METI, GENIAC and 16 AI-model projects; Digital Agency, Government AI GENAI
- UAE ATRC, Falcon H1 and Falcon Arabic; Saudi SDAIA, National Data and AI Strategy
- IndiaAI, Compute policy and AI cloud portal
- Vietnamese Government, National Data Strategy and AI Law; SCB 10X, Typhoon; Masakhane