Showing posts with label Developer Tools. Show all posts

Tuesday, July 28, 2026

WebMCP and Browser AI: When Agents Call Tools Instead of Clicking

When people imagine AI agents working on the web, they often picture software that clicks through pages the way a person would. In practice, that approach is fragile. Button positions change, pop-ups interrupt flows, and the same form can expose different DOM structures depending on a user’s state. WebMCP, introduced by the Google Chrome team at I/O 2026, is an attempt to solve that problem at the web-platform layer.

The central idea is that a website can explicitly tell browser-based agents which structured tools are safe to call. A user grants permission, and the agent works with machine-readable functions or forms instead of guessing from pixels and markup. If remote MCP is about connecting agents to servers and tools, WebMCP focuses on the boundary between the browser and the web page itself. That makes browser AI less like a screen-scraping bot and more like a permissioned runtime for web agents.

Background

In Chrome’s announcement, WebMCP was described as a proposal for turning websites into agentic toolkits. The experimental origin trial is planned for Chrome 149, and Gemini in Chrome is expected to support WebMCP APIs. Google’s I/O 2026 developer keynote recap placed Modern Web Guidance, Chrome DevTools for agents, and Chrome built-in AI APIs in the same workflow. The direction is clear: agents should be able to build code, verify it in the browser, and interact with web services under user-approved constraints.

That matters because the hardest failure points for agentic AI outside the app sandbox usually sit at the interface layer. A language model may write fluent text, but workflows such as payment, booking, account changes, and applications depend on permissions, state, validation, and cancellation paths. WebMCP is less about “what did the agent click?” and more about “which intention was executed, through which declared capability, under which limits?”

Area Screen-clicking agent WebMCP-style approach
Target Buttons, fields, DOM layout Declared functions, forms, and site tools
Typical failure Layout changes, pop-ups, hidden state Permission design, tool schemas, server validation
User control Watching the screen and undoing later Approval before calls and scoped permissions
Developer focus Stabilizing UI automation Tool definitions, audit logs, exception handling

How It Works

Consider a travel-booking site. A conventional agent has to type departure and arrival cities, open a date picker, click filters, and read the results. In a WebMCP-style design, the site can expose callable capabilities such as searchFlights, holdReservation, or compareHotelOptions. The agent calls those tools only within the scope the user has approved, shows the result to the user, and asks for fresh confirmation before sensitive steps such as payment.
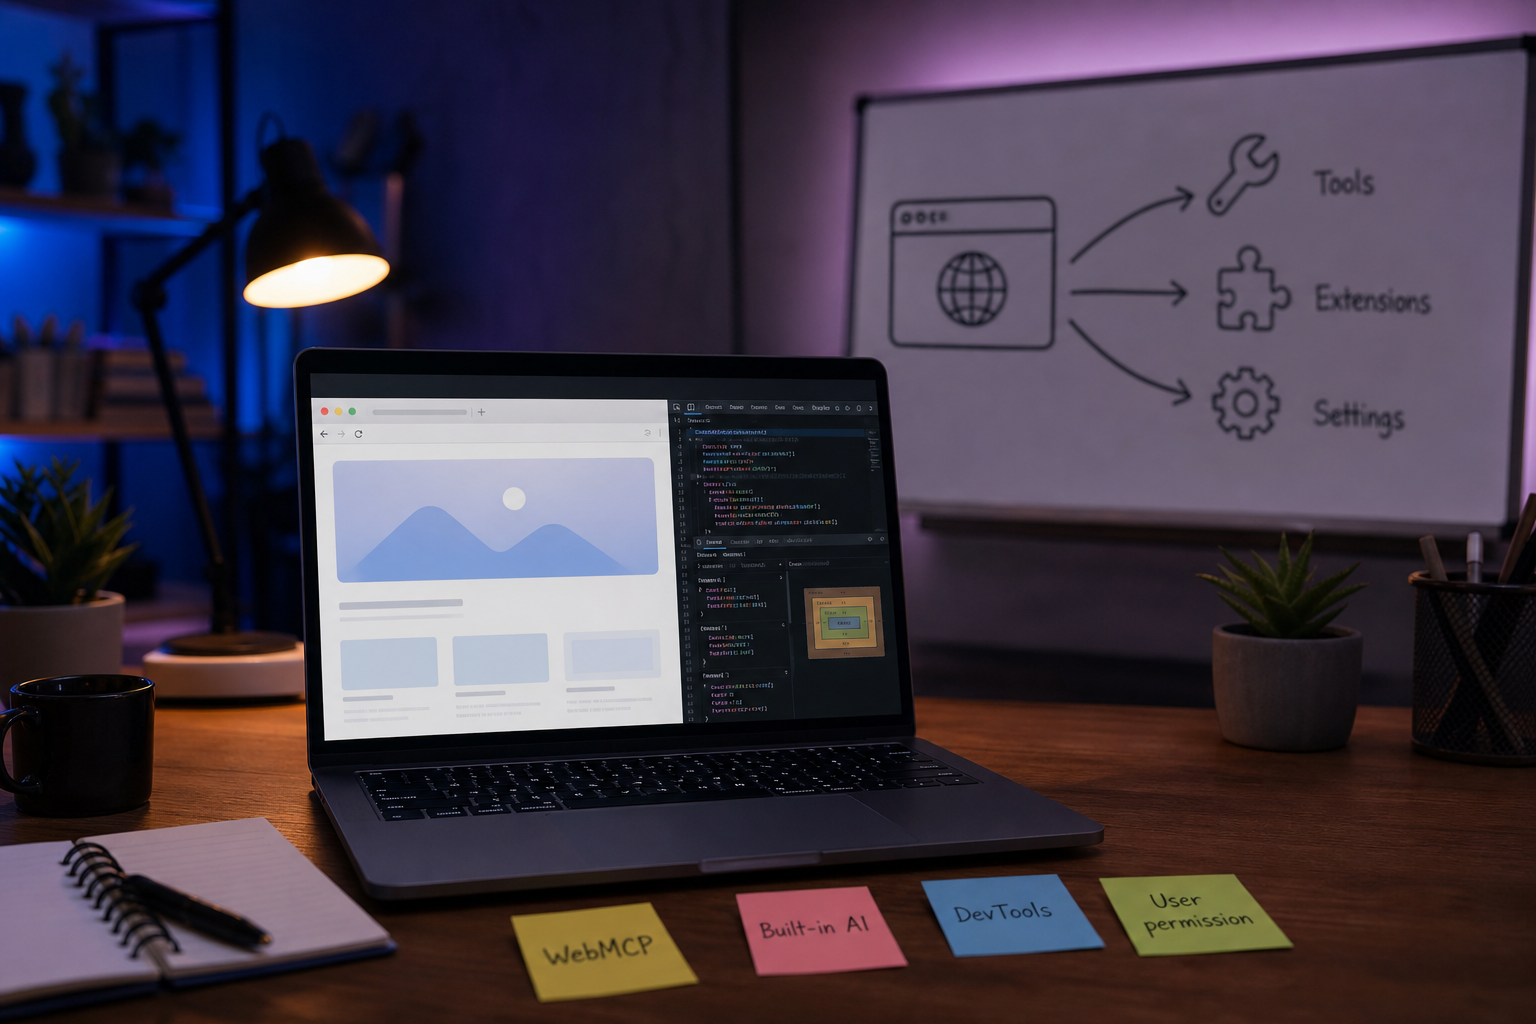
Browser AI workstation — a laptop and whiteboard showing the relationship between WebMCP, built-in AI, and DevTools

<How models, declared site tools, and developer verification meet inside the browser 2.1>

Chrome built-in AI belongs to the same shift. If translation, language detection, and future writing or summarization features can run in the browser, some product experiences can reduce server calls, latency, and the movement of private text. That does not mean every model runs locally on every device with equal speed. Chrome’s framing is that the browser can manage models and share optimized execution across sites. For developers, the new question becomes: before sending a task to a server-side API, can the browser perform it safely and well enough?

Architecture

Adding WebMCP to a product does not make a site autonomous by itself. The practical structure has four layers. First, the web app defines callable tools and their input schemas. Second, the browser exposes those tools to an agent in a controlled way. Third, the user approves the relevant account, price, and personal-data boundaries. Fourth, the server still validates final authority and business rules.
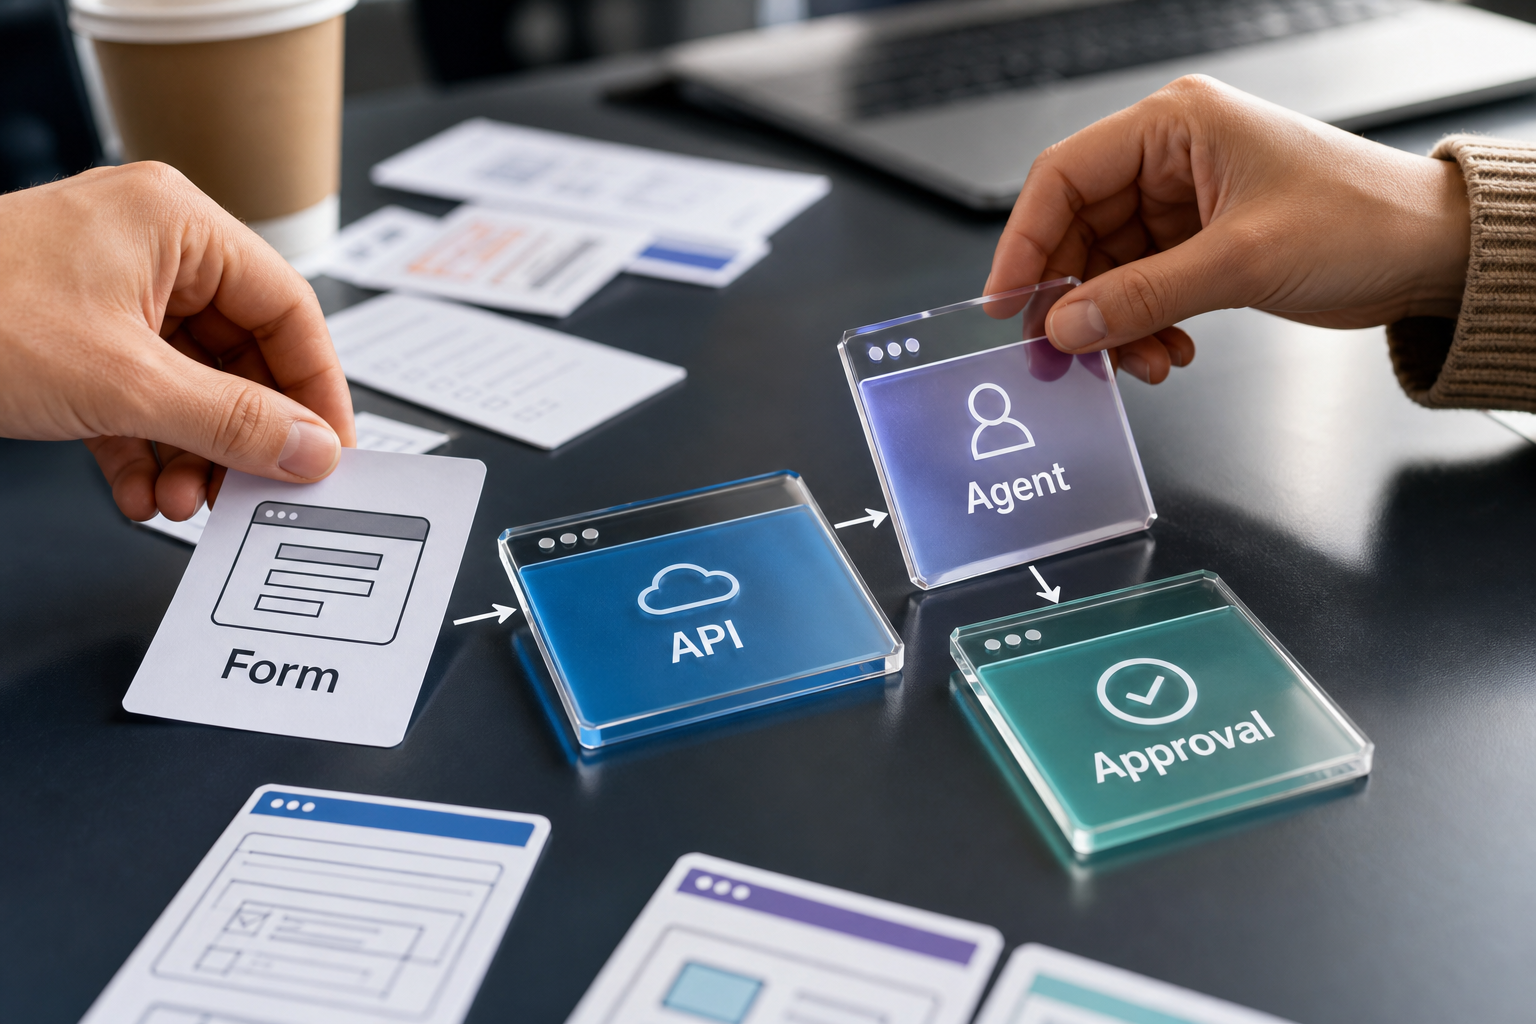
WebMCP tool cards — hands arranging Form, API, Agent, and Approval cards on a table

<A web-agent workflow that favors explicit tool calls over brittle screen automation 3.1>

This also changes developer tooling. Chrome DevTools for agents gives agents access to console logs, network traffic, and accessibility trees, so they can reproduce and diagnose issues in a real browser. Instead of a human simply saying “test it,” an agent can inspect performance and accessibility evidence and propose fixes. Even then, responsibility stays with the delivery pipeline. The more automated fixes become, the more important tests, rollback paths, audit logs, and product readiness checks become.

Checkpoints

  • WebMCP is still closer to a proposal and an experiment than a fully settled deployment baseline. Teams should track conditions such as the Chrome 149 origin trial and limit experiments to well-bounded flows.
  • The tools exposed by a site become a new attack surface. Input validation, permission separation, rate limits, and reconfirmation for sensitive actions need to be part of the design from the start.
  • Browser built-in AI can reduce cost and latency, but model availability, device performance, and browser support differences can fragment the experience.
  • Users need to understand what an agent did. A good interface should show which data was checked and which choices were deferred, not just say that a task is complete.

The significance of WebMCP is not that websites should hand every action to AI. It is almost the opposite. It separates user-approved scope, site-defined tools, and server-enforced rules so that an agent’s behavior becomes narrower and more explicit. For web-service teams, the useful question is not whether the demo looks impressive. It is which actions in the product can be expressed as safe, auditable tools.

Sunday, July 26, 2026

CodeRabbit AI PR Reviews: Where Automated Code Review Fits

CodeRabbit is an AI code review tool that reads a pull request, summarizes the change, leaves line-level comments, and suggests fixes when a PR is opened. It integrates with GitHub, GitLab, Azure DevOps, Bitbucket, and similar Git platforms, and it is best understood as a “first reviewer” inside the pull request workflow. It is not primarily a code generator; it is an automation layer that flags risky changes and missing context before a human reviewer spends attention on the PR.

The review bottleneck in many teams now appears after code is written, not before it. AI coding tools can increase the number and speed of pull requests, but senior reviewer time does not scale at the same rate. Tools such as CodeRabbit try to close that gap by separating the work of static analysis, LLM-based contextual review, and human design judgment.

Background: Faster PRs Make Review the Bottleneck

CodeRabbit’s official documentation says the product automatically performs a full review when a new pull request is opened and then performs incremental reviews focused on newly pushed commits. It also highlights bug detection, one-click fixes, full-repository context, and links to issue trackers as part of the review workflow. On GitHub Marketplace, CodeRabbit is listed as a verified GitHub App, and the public listing shows more than 290,000 installs.

Those figures do not prove review quality by themselves. They do show that AI review has moved from experimental plugin territory into the always-on PR workflow. DeployHQ’s experience write-up frames CodeRabbit the same way: not as a replacement for human judgment, but as an extra layer that can surface problems before deployment.

A software team in a meeting room reviewing a pull request workflow with automated and human review stages

<Automated checks and human judgment arranged in a pull request review workflow 1.1>

How It Works: Static Analysis, LLMs, and Humans Review Different Things

The key to using CodeRabbit well is avoiding the claim that AI can finish every review. Each layer sees a different class of problem. Linters and SAST tools are strongest when the rule is explicit: unused variables, formatting violations, known vulnerability patterns, type mismatches, and similar checks. That is the territory where GitHub Code Quality, CodeQL, and related gates fit naturally.

LLM review works in a different zone. It can ask whether a changed function still fits the existing design, how error handling affects callers, whether tests cover the requirement’s main path, and whether a performance or maintainability issue hides inside otherwise valid code. CodeRabbit’s documentation gives examples such as bugs static analyzers miss, architecture suggestions based on the whole repository, performance bottlenecks in logic, and maintainability problems.

Human review should still make the final decision. Product intent, incident responsibility, long-term architecture, and risk acceptance are difficult to delegate to a tool. PR security review especially requires distinguishing a possible vulnerability from an operationally relevant risk. An AI comment should trigger investigation; it should not become the approval rule by itself.

Review layer What it handles well Main limitation Best team role
Static analysis and SAST Rule-based errors, vulnerable patterns, style violations Weak product and design context Automated pre-merge gate
LLM review Change summaries, missing tests, suspicious logic flow Noise and incorrect assumptions First pass and question generator
Human review Design ownership, product judgment, risk acceptance Time, fatigue, missed context Final approval and exception handling

Structure: What Happens Inside a GitHub PR

CodeRabbit’s GitHub integration documentation says installation requires repository or organization owner permissions. During setup, teams can grant access to all repositories or only selected repositories. The app requests read/write access to code, commit statuses, issues, and pull requests so it can review code and manage PR-related workflows. The documentation also says CodeRabbit does not retain source code after review except when review caching is enabled, but teams handling proprietary code should still review caching, external integrations, the Trust Center, and contractual terms before rollout.

Once a PR opens, CodeRabbit summarizes the change and leaves line-level comments. When new commits are pushed, it reviews what changed since the previous review rather than repeating the entire process each time. Developers can control the bot from PR comments with commands such as @coderabbitai pause, resume, review, full review, resolve, approve, and summary to pause automated review, request a fresh full review, resolve comments, or update the PR summary.

A developer desk with a laptop, checklist cards, security key, and notebook showing layered code review checks

<Checklist view of static analysis, AI review, and human code review 3.1>

A practical flow looks like this:

  1. A developer makes a branch and opens a pull request.
  2. Existing CI and static analysis flag rule-based problems first.
  3. CodeRabbit comments on change intent, risky logic, missing tests, and possible fixes.
  4. The developer applies some suggestions and explains comments that do not match the repository context.
  5. A human reviewer checks the remaining design, security, and product decisions before merge.

Adoption Checklist: Automated Review Does Not Replace Team Rules

First, teams need to prevent overtrust. A CodeRabbit comment is a starting point for review, not an approval basis by itself. For code involving security, payments, permissions, or data deletion, keep a separate checklist and human approval even when the AI says the change looks safe.

Second, repository permissions and data policy should be settled before rollout. GitHub App permissions are necessarily broad for a review tool. Public repositories and private product repositories may need different rules. Review caching, external tool connections, and issue-tracker linking should be limited according to the team’s security policy.

Third, teams should manage the noise budget. If every warning becomes mandatory work, the review process may get slower instead of faster. During the first rollout, define categories such as “must fix,” “discuss,” and “safe to ignore,” then tune configuration files and team guidelines to reduce repeated false positives.

Code review checklist

  • Start with small PRs and measure comment accuracy and review time.
  • Keep human review mandatory for security, permission, and migration changes.
  • Use full review only for large changes or changed review criteria to reduce cost and noise.
  • Document coding rules, test expectations, and ignorable warnings so repeated comments decline over time.

CodeRabbit’s value is less about removing reviewers and more about helping reviewers spend attention on better questions. Static analysis enforces explicit rules, AI review raises contextual questions early, and people judge design and risk. If a team starts with a small repository and tunes comment quality, security policy, and response habits, GitHub PR automation can improve not only review speed but the way code quality is managed.

Sources

404 Dev Room 30 - Taming

Series · 404 Dev Room Webtoon · Ongoing Episode 30 · 404 Dev Room 30 - Taming The trainer in the AI coding room has changed. <...